MLX and Apple Silicon
Running open-weight models efficiently on Mac hardware, on our own fork of Apple's MLX.
Lab
We test what we build. The lab is where we run local models, measure them and harden the agent controls that go into our servers.
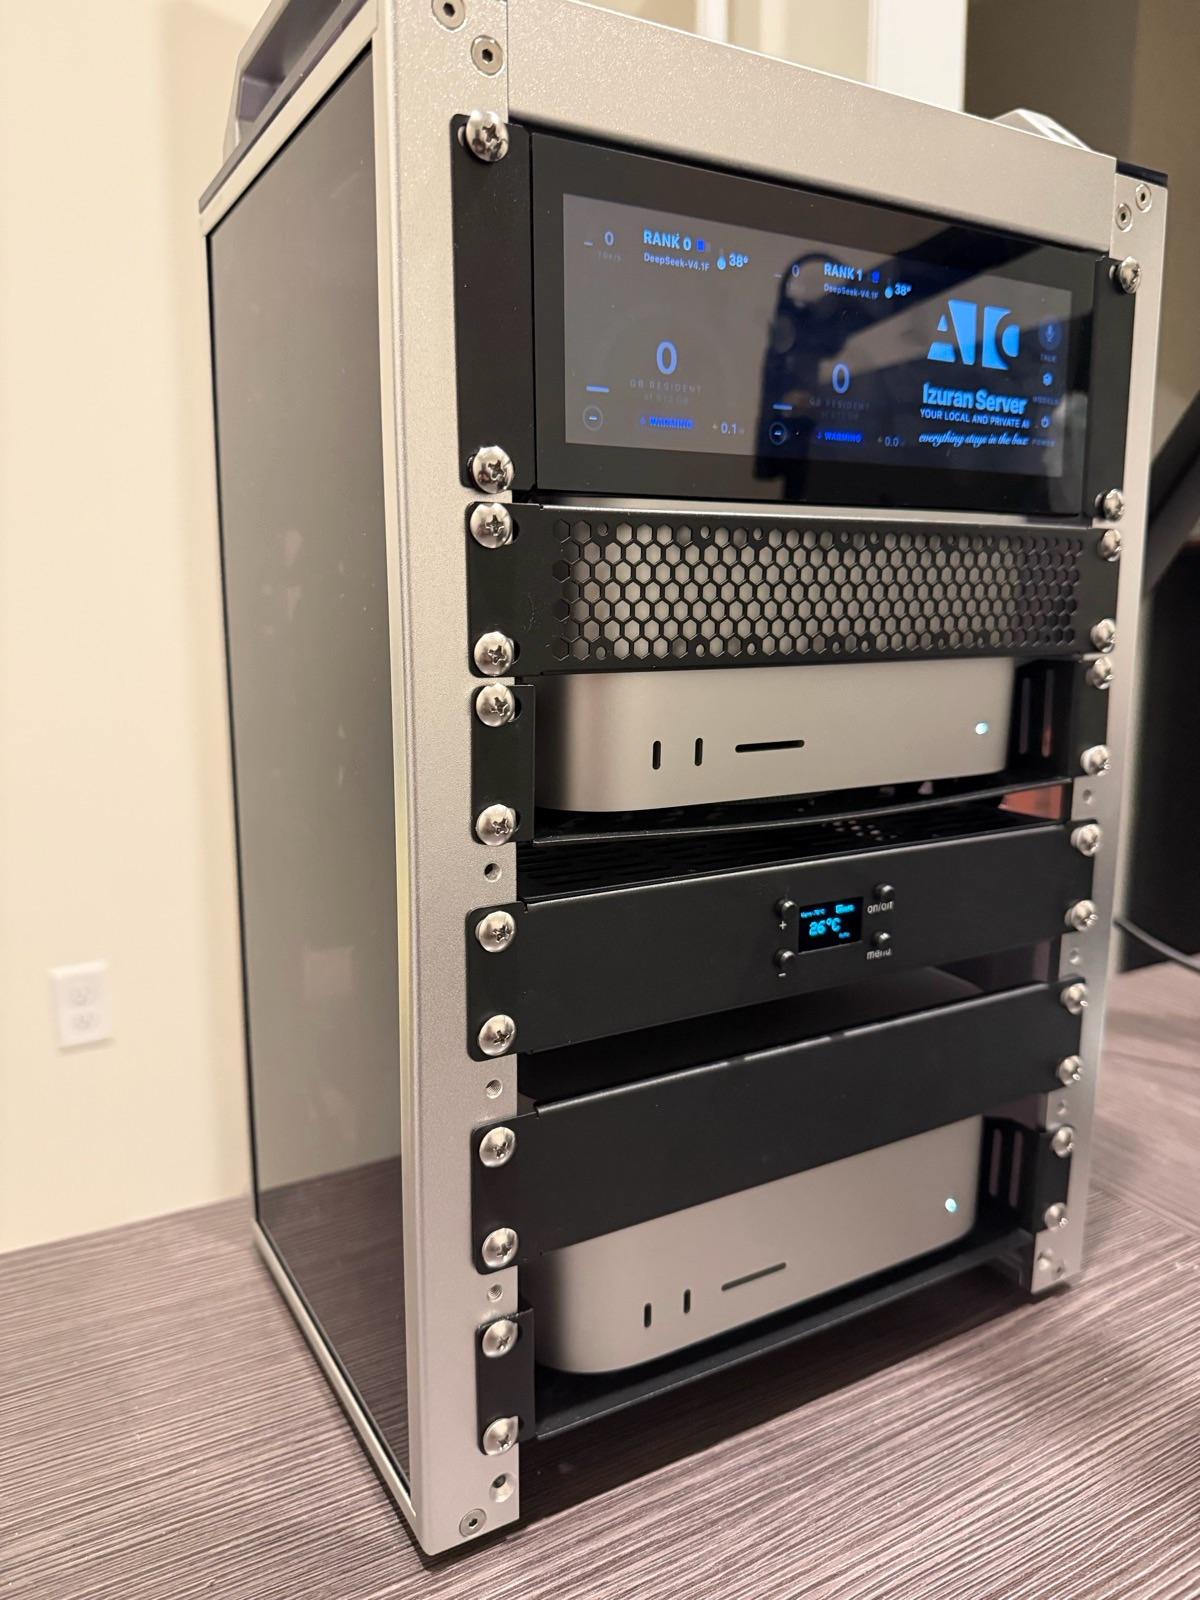
Two Mac Studios joined by one Thunderbolt 5 cable serve the largest open-weight models as a single server. Models like GLM-5.3 and DeepSeek V4.1 Flash are too big for one Mac, so they run split across both.
The engine is ours: a production-grade inference server we built on Apple's MLX, the same one that runs in the servers we deliver.
Request a quote for this rack →Running open-weight models efficiently on Mac hardware, on our own fork of Apple's MLX.
One Mac, copies on several Macs, or one model split across two, and what it takes to make that reliable in an office.
The controls around an agent: approvals, the network fence around its commands, and the logs.
Every model and quantization tested on agent tasks before it enters our catalog.
Teaching smaller models to use tools well, with adapters for each environment.
Izuran's voice and its end-of-turn detection run on Apple's Neural Engine.
We publish what fits on each size of Mac, with the peak memory and speed we measured, from a 64 GB Mac mini to two Mac Studios.
See the models and Macs →When a Mac leaves the lab, we test it, erase it and grade it, and sell it through AIC Lab Store.
Visit AIC Lab Store →